iFANN
    搜索 iFANN...
    登录
    首页
    新闻
    视频
    图片
    GIF
    探索
    投票
    大奖
    iFAMOUS
    维基
    动漫
    聊天室
    通知
    私信
    收藏
    我的
    维基大奖iFAMOUS排行榜行业创作者奖励用户奖励条款隐私社区准则下架 / DMCA帮助开发者

    © 2026 iFANN

    首页
    搜索
    私信
    提醒
    我的
    照片
    Nate
    Nate@nate_5121d
    ⭐Andrej Karpathy🏢Google📱Qwen
    Google WikiSkill paper SKILL.md agents

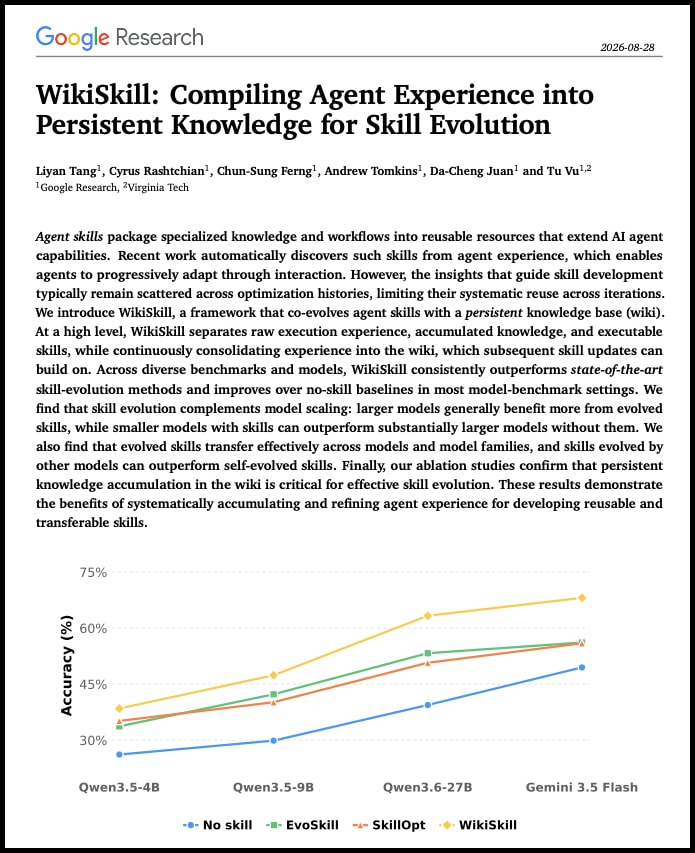
    @nate_512The graph in that Google paper is what got me. Qwen-9B with evolved skills posts 47.4% across five benchmarks. Qwen-27B running bare posts 39.4%. Both Qwen, neither one fine-tuned. Smaller model wins. What skill evolution actually does: the agent takes a swing at a task, reads back its own traces, rewrites its own skill set, and keeps the rewrite only when validation says it helped. EvoSkill, SkillOpt, Trace2Skill all trip on the same thing, the lessons worth keeping end up buried in optimizer history instead of anywhere reusable. WikiSkill's fix is a wiki that lives between the traces and the skills. Karpathy's LLM Wiki is the inspiration. After every run a maintainer sorts the wins and the misses into that wiki, a proposer reads it and edits SKILL.md, and anything that turns out bad rolls back on its own. Numbers back it. WikiSkill clears the best prior method by 3.3 to 12.0 points on all five models tested. The bigger the model the more it gains: 12.3 points on Qwen 4B, 17.5 on 9B, 23.9 on 27B. Skills also travel. Qwen-27B wrote them, Qwen-9B picked them up, SpreadsheetBench went 24.3% to 50.5%. And the wiki is not decorative. Take it out and Gemini 3.5 Flash falls from 63.7% to 48.7%. Most skills out there are still written by hand. A bigger model is not the only way up. Test what evolved skills squeeze out of the one you already own first

    查看原帖
    Google WikiSkill paper SKILL.md agents

    @nate_512 的照片· Sep 20, 2026· Andrej Karpathy

    关于这张照片

    The image is a screenshot of a research paper. The focus is on the title "WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution" and a line graph showing accuracy percentages across different models. The mood is academic and informative. Visually notable elements include the Google Research logo and the graph itself, which displays four distinct lines representing different skill evolution methods. ON-SCREEN TEXT: Google Research 2026-08-28 WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution Liyan Tang¹, Cyrus Rashtchian¹, Chun-Sung Ferng¹, Andrew Tomkins¹, Da-Cheng Juan¹ and Tu Vu¹,² ¹Google Research, ²Virginia Tech Accuracy (%) 75% 60% 45% 30% Qwen3.5-4B Qwen3.5-9B Qwen3.6-27B Gemini 3.5 Flash -•- No skill -EvoSkill -SkillOpt -WikiSkill

    查看Andrej Karpathy的全部照片阅读Andrej Karpathy维基

    ?

    更多Andrej Karpathy照片

    查看Andrej Karpathy的全部照片
    Andrej Karpathy ChatGPT graph engineeringAndrej Karpathy ChatGPT graph engineeringGraphify open source toolGraphify open source toolKarpathy Stanford AI engineering lectureKarpathy Stanford AI engineering lectureClaude Code + Obsidian Second Brain setupClaude Code + Obsidian Second Brain setupAndrej Karpathy interviewAndrej Karpathy interview
    照片
    Nate
    Nate@nate_5121d
    ⭐Andrej Karpathy🏢Google📱Qwen
    Google WikiSkill paper SKILL.md agents

    @nate_512The graph in that Google paper is what got me. Qwen-9B with evolved skills posts 47.4% across five benchmarks. Qwen-27B running bare posts 39.4%. Both Qwen, neither one fine-tuned. Smaller model wins. What skill evolution actually does: the agent takes a swing at a task, reads back its own traces, rewrites its own skill set, and keeps the rewrite only when validation says it helped. EvoSkill, SkillOpt, Trace2Skill all trip on the same thing, the lessons worth keeping end up buried in optimizer history instead of anywhere reusable. WikiSkill's fix is a wiki that lives between the traces and the skills. Karpathy's LLM Wiki is the inspiration. After every run a maintainer sorts the wins and the misses into that wiki, a proposer reads it and edits SKILL.md, and anything that turns out bad rolls back on its own. Numbers back it. WikiSkill clears the best prior method by 3.3 to 12.0 points on all five models tested. The bigger the model the more it gains: 12.3 points on Qwen 4B, 17.5 on 9B, 23.9 on 27B. Skills also travel. Qwen-27B wrote them, Qwen-9B picked them up, SpreadsheetBench went 24.3% to 50.5%. And the wiki is not decorative. Take it out and Gemini 3.5 Flash falls from 63.7% to 48.7%. Most skills out there are still written by hand. A bigger model is not the only way up. Test what evolved skills squeeze out of the one you already own first

    查看原帖
    Google WikiSkill paper SKILL.md agents

    @nate_512 的照片· Sep 20, 2026· Andrej Karpathy

    关于这张照片

    The image is a screenshot of a research paper. The focus is on the title "WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution" and a line graph showing accuracy percentages across different models. The mood is academic and informative. Visually notable elements include the Google Research logo and the graph itself, which displays four distinct lines representing different skill evolution methods. ON-SCREEN TEXT: Google Research 2026-08-28 WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution Liyan Tang¹, Cyrus Rashtchian¹, Chun-Sung Ferng¹, Andrew Tomkins¹, Da-Cheng Juan¹ and Tu Vu¹,² ¹Google Research, ²Virginia Tech Accuracy (%) 75% 60% 45% 30% Qwen3.5-4B Qwen3.5-9B Qwen3.6-27B Gemini 3.5 Flash -•- No skill -EvoSkill -SkillOpt -WikiSkill

    查看Andrej Karpathy的全部照片阅读Andrej Karpathy维基

    ?

    更多Andrej Karpathy照片

    查看Andrej Karpathy的全部照片
    Andrej Karpathy ChatGPT graph engineeringAndrej Karpathy ChatGPT graph engineeringGraphify open source toolGraphify open source toolKarpathy Stanford AI engineering lectureKarpathy Stanford AI engineering lectureClaude Code + Obsidian Second Brain setupClaude Code + Obsidian Second Brain setupAndrej Karpathy interviewAndrej Karpathy interview