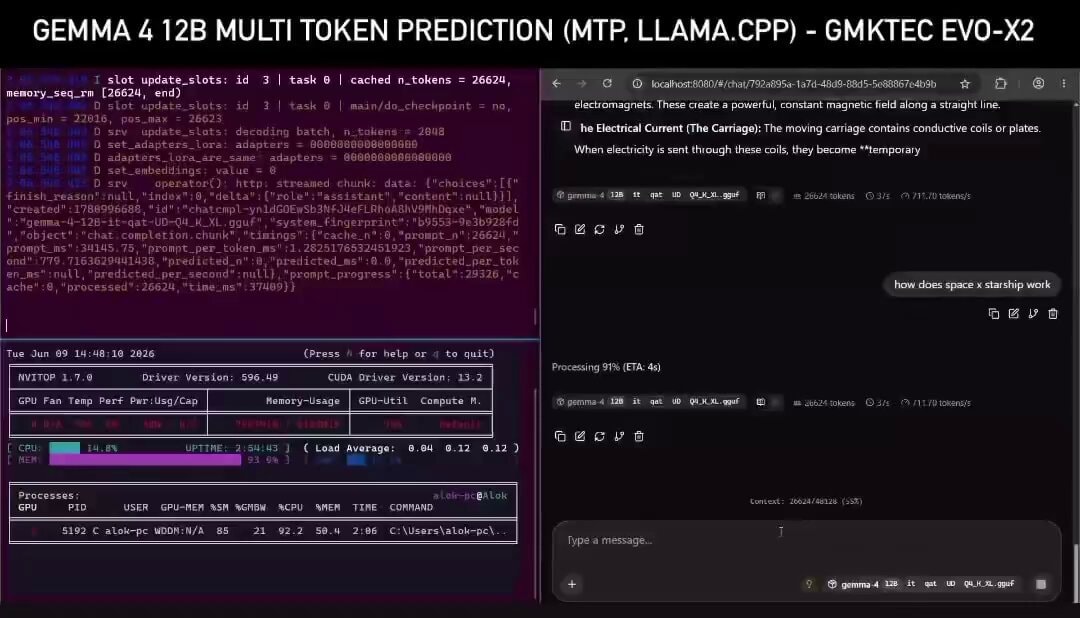
Gemma-4-12B running at 711 tok/s on AMD GPU
An AMD engineer just demonstrated something remarkable on camera. The clip captures it all in a single frame: llama.cpp slot logs on the left, nvitop showing a steady 79% GPU utilization, and a localhost chat answering a 26,000-token prompt at 711 tok/s prompt eval for the gemma-4-12B model. You can see the full setup at
文字记录 (en)
I